Qwen-Image-2.1 Review: Transparent Images, Editing, API Pricing and NSFW
Qwen-Image-2.1 reviewed: transparent PNGs, reference editing, real user feedback, API costs, ComfyUI setup, VRAM and research-license limits.


Qwen-Image-2.1 is most interesting as an editable asset generator: it can create transparent images, work with several references and revise an existing picture in one model. For someone experimenting with stickers, product cutouts or character variations, that is more useful than another promise of prettier pictures.
The catch is substantial: the downloadable weights use a research license, and the advertised 7B size covers only the visual generator. Try the official demo before buying hardware, and resolve commercial licensing before putting a local installation into a paid workflow. Information and prices checked on September 24, 2026.
Updated October 13, 2026: official Turbo release, setup and API pricing added. Qwen-Image-2.1-Turbo: the official 8-step update
What changed in Qwen-Image-2.1?
Released on September 20, 2026, Qwen-Image-2.1 combines text-to-image generation and editing. Its main upgrades are native alpha transparency, up to ten reference images, localized edits guided by annotations or masks, and a smaller 7B visual generator. Qwen also claims better lettering, portrait lighting and textures; those are vendor claims, not proof that every prompt improves.

| Feature | Why it matters | What to check |
|---|---|---|
| Native RGBA | Create an isolated asset without a separate cutout pass. | Inspect hair, glass and soft edges on light and dark backgrounds. |
| Up to 10 references | Combine people, objects or clothing from separate inputs. | More inputs can increase cost in time and reduce clarity of instructions. |
| Native 2K | Default documented square output is 2048 × 2048. | Higher resolution needs more runtime memory. |
| Unified checkpoint | Generate and edit without switching between separate model families. | An existing 2511 workflow is not automatically compatible. |
| 7B visual generator | Smaller generation component. | The Qwen3-VL 8B encoder and VAE also occupy memory. |
A transparent background is an alpha channel, not a checkerboard drawn into an opaque picture. Export PNG and place it over another image to verify the result. The model’s maximum reference count is a capability ceiling, not a promise of flawless ten-person compositions.
Qwen-Image-2.1-Turbo: the official 8-step update
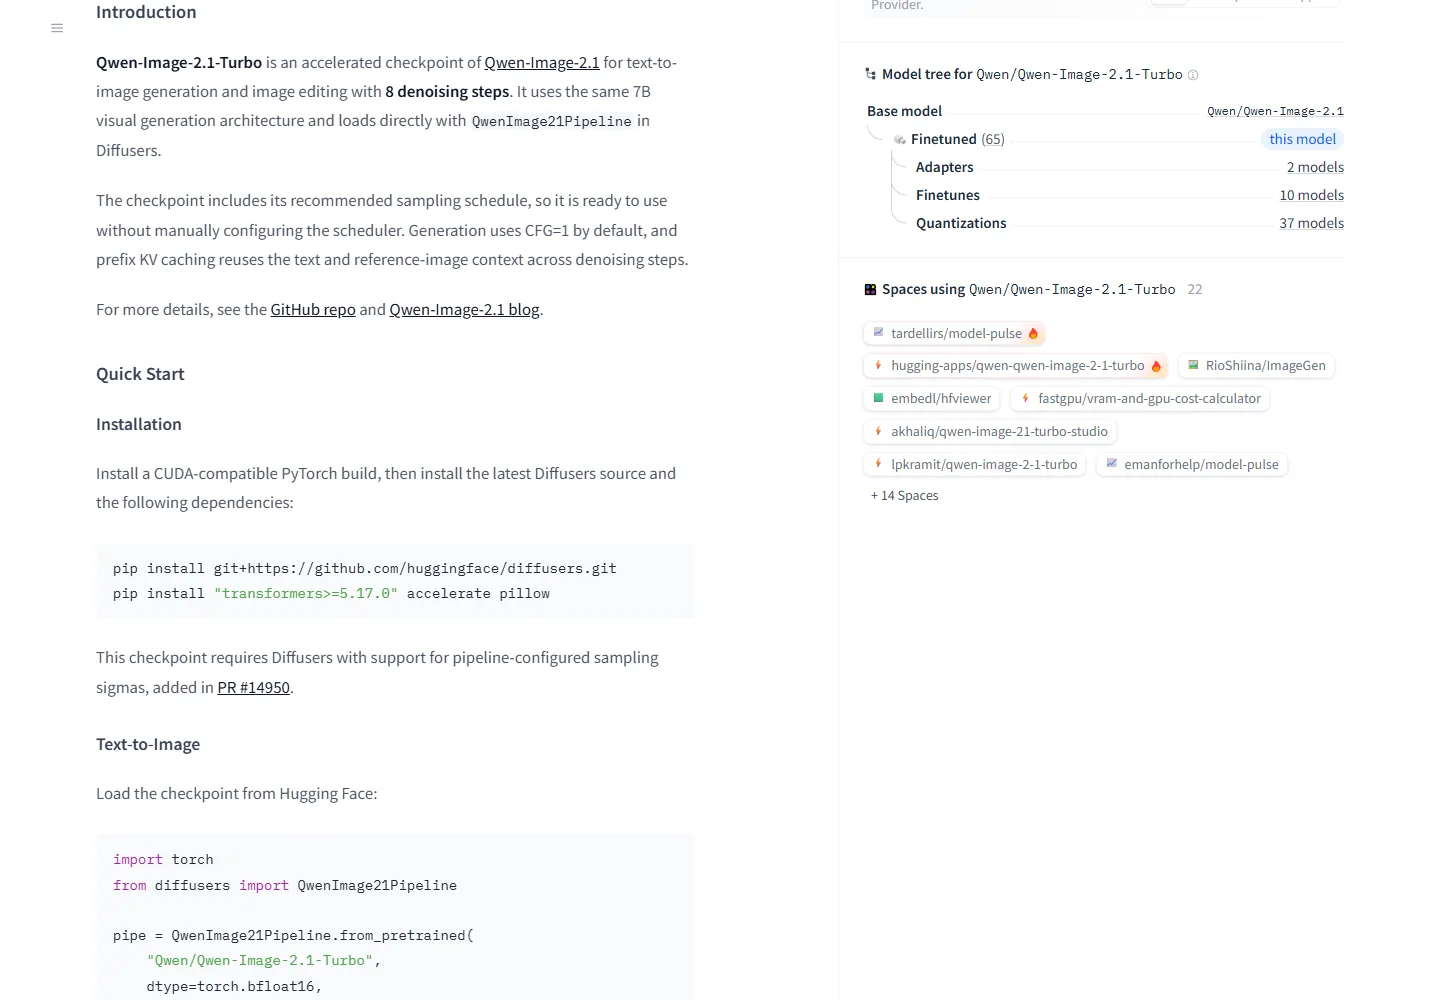
Qwen released Qwen-Image-2.1-Turbo on October 9, 2026. It is an accelerated checkpoint for both generation and editing, retaining the 7B visual architecture and using eight denoising steps. The original model remains useful as a comparison baseline. Turbo is especially worth testing when repeated edits or prompt iterations make waiting time the main bottleneck.
What Turbo changes—and which “Turbo” you are downloading
There are three different downloads to distinguish: the official full Turbo checkpoint; Comfy-Org’s extracted Turbo LoRA for the original base; and earlier community accelerators such as Viggle. They are not interchangeable presets. For a clean first comparison, use the official checkpoint without an additional acceleration LoRA. Do not stack the extracted accelerator on top of an already distilled full Turbo model.
The original repository’s generation example uses 40 steps, while Turbo uses a saved eight-step schedule and defaults to CFG=1. That is an 80% reduction in the example’s denoising-step count, not proof of five-times-faster total generation. Text encoding, reference processing, model loading, offloading and VAE decoding still take time. Prefix KV caching reuses text and reference context across steps.
Qwen GitHub · Qwen-Image-2.1-Turbo
Run the official checkpoint with Diffusers
Install a CUDA-compatible PyTorch build first. In a separate environment, install current Diffusers source with support for pipeline-configured sampling sigmas—introduced in PR #14950—and transformers 5.17.0 or newer. An older environment that runs the original model can still mishandle Turbo. The following short prompt is a suggested example, not a claimed test result.
python -m pip install git+https://github.com/huggingface/diffusers.git
python -m pip install "transformers>=5.17.0" accelerate pillow
import torch
from PIL import Image
from diffusers import QwenImage21Pipeline
pipe = QwenImage21Pipeline.from_pretrained(
"Qwen/Qwen-Image-2.1-Turbo",
dtype=torch.bfloat16,
).to("cuda")
image = pipe(
prompt="A studio photo of a blue ceramic cup on a wooden table, soft window light.",
width=2048,
height=2048,
use_kv_cache=True,
generator=torch.Generator("cpu").manual_seed(42),
).images[0]
image.save("turbo-generation.png")
source = Image.open("input.png").convert("RGBA")
edited = pipe(
prompt="Change the cup to white. Preserve its shape, camera angle, table and lighting.",
image=source,
width=2048,
height=2048,
use_kv_cache=True,
generator=torch.Generator("cpu").manual_seed(42),
).images[0]
edited.save("turbo-edit.png")Let the pipeline load the checkpoint’s recommended schedule. Changing num_inference_steps alone does not replace it; an explicit sigmas argument does, but alternative schedules are not validated by the official model card. For editing, reuse the pipeline, load your own input image as RGBA and describe both the intended change and what must remain intact. Start with one reference and a fixed seed before adding complexity.
model_index.json — sample_sigmas
Use Turbo in ComfyUI
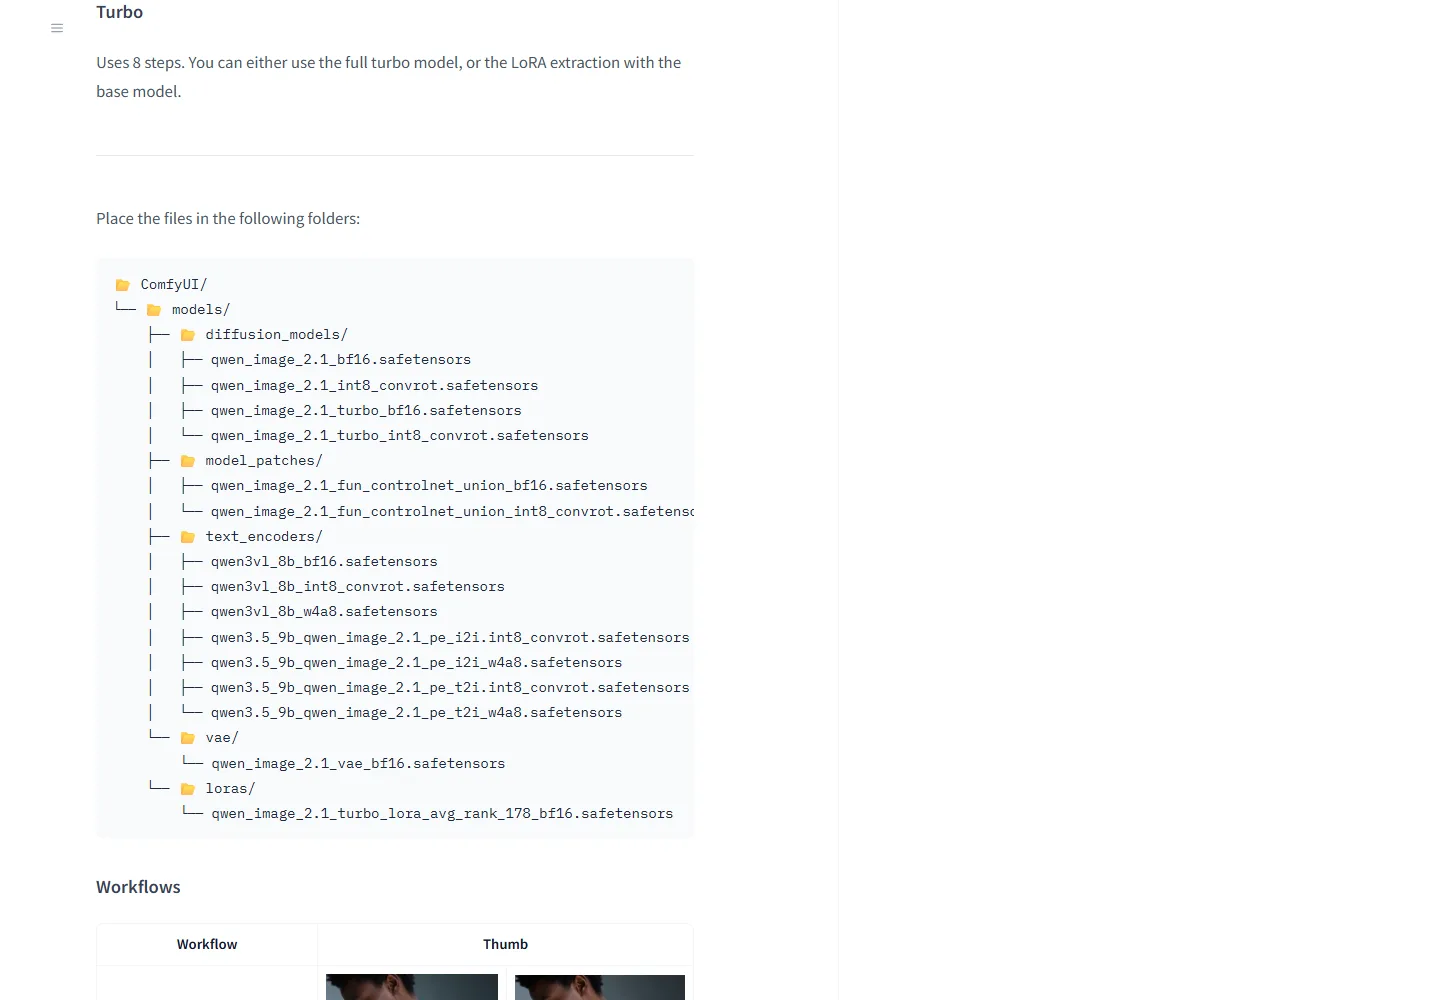
- Update ComfyUI and obtain compatible files from Comfy-Org/Qwen-Image-2.1. The full Turbo BF16 or INT8 ConvRot diffusion file belongs in models/diffusion_models.
- Use the matching Qwen3-VL 8B encoder in models/text_encoders and qwen_image_2.1_vae_bf16.safetensors in models/vae. Do not substitute the older Qwen-Image VAE or a 2511 editing workflow.
- Start from a current Qwen-Image-2.1 workflow and select the Turbo diffusion file. Use eight steps, CFG 1 and the Turbo-compatible sigma schedule. A generic eight-step scheduler is not automatically equivalent to the saved schedule.
- If choosing the extracted LoRA route instead, load the original 2.1 base and the extraction in models/loras. Keep this as a separate workflow from the full Turbo route.
- Generate a baseline with no stylistic LoRAs. Then add references or other adapters one at a time, inspecting fine text, alpha edges and identity after each change. Use the linked model configuration as the schedule reference when a workflow requires manual sigmas.
Speed, detail and what early users report
Early community results suggest that editing speed is a useful reason to try Turbo, but reactions to text-to-image detail are mixed. One 2K/manual-sigma discussion reports reduced block artifacts together with overly smooth skin; other participants question fabric detail. A separate side-by-side post compares the original plus an extracted accelerator with the full Turbo, both at eight steps. These are configuration-specific observations, not controlled evidence that every Turbo output is worse or better.
For your own comparison, keep the source image, prompt, resolution, seed and prompt-enhancement setting fixed. Compare several seeds and inspect at full size: small lettering, skin texture, repeated patterns, product logos and the areas that an edit was supposed to preserve. Test transparent PNGs on both a light and dark background. Do not hide failures by comparing only each model’s best image.
Reddit: 2K / sigmas · Reddit: Turbo / LoRA
Hardware: fewer steps does not mean a tiny model
The 7B figure describes the visual generator, not the full runtime. Comfy-Org lists the Turbo diffusion file at about 14.2GB in BF16 or 7.26GB in INT8 ConvRot; the encoder, VAE, activations and reference images are additional. These are download sizes, not VRAM requirements. Fewer steps shorten repeated computation but do not shrink all weights. If memory is tight, use supported quantization/offloading and test fewer references before buying a GPU; offloading can reduce the speed advantage.
Official online access, API cost and licensing
The official release also links Alibaba Cloud Model Studio’s Turbo API and its online model experience. Select the exact model ID qwen-image-2.1-turbo, the available region and the corresponding API key/endpoint; the original model’s HF demo or a third-party page is not proof that Turbo is selected. The published rate is US$0.016 per image in Singapore, or US$0.014133 in the listed global deployments such as Tokyo and Frankfurt. That is US$1.60 or US$1.4133 for 100 images before applicable extras. The documentation lists 120 requests/minute; this is a rate limit, not a latency guarantee. Availability, account quotas and billing region still matter.
Alibaba Cloud Model Studio — Turbo · qwen-image-2.1-turbo — API
Downloaded Turbo weights retain the Qwen Research License: research/evaluation use is the default grant, with a separate license required for commercial use of the model materials. Hosted API service terms and local-weight licensing are separate. Turbo also does not establish unrestricted NSFW support: hosted moderation and the original model’s limitations still apply. Faster sampling is not a safety-policy or license change.
Should you switch from the original model?
Start with Turbo for rapid editing experiments, reference-based drafts and prompt iteration. Keep the original 2.1 workflow when fine texture, a particular LoRA or strict preservation matters, and compare actual outputs before switching. If your main goal is deployable production access, evaluate the official API’s price and service terms separately from the cost of running downloaded weights.
What early users actually report
Europa Press covered the release and its transparency features, but launch reporting is not an independent quality test. The useful early evidence comes from users showing their own outputs and configurations.
In a Hugging Face hands-on report, TheTechnoX ran INT8 models in ComfyUI on an RTX 4060 Ti 16GB and described successful localized editing. Their approximate timings were 20 seconds for generation and 60 seconds for editing, with roughly 15GB peak VRAM. Resolution and step count were not fully specified, so these numbers are an example of feasibility, not a speed guarantee.
A separate Reddit review found expression, pose and background changes useful, but criticized yellowish tones, grain and synthetic-looking results in some generations. It also found complex multi-element combinations less convincing. That is a reason to test your own briefs rather than assume every reference-heavy job will work.
Our assessment: evaluate it first for controlled edits and transparent assets. Photorealism and complicated compositions need closer inspection. These observations are attributed early user reports; this review does not present them as an AirMore GPU benchmark.
Where to try it online and what the API costs
The official Qwen Hugging Face demo is the clearest online entry point for this exact model. It supports English and Chinese prompts, optional input images and a prompt-enhancement switch. Shared demo capacity can change; there is no verified unlimited-generation entitlement or production SLA.

- Open the demo and start with no uploaded image for text-to-image.
- Enter one clear description. For editing, upload your own image and specify the change and what must remain unchanged.
- For transparency, explicitly ask for RGBA with a transparent background. Keep the output as PNG.
- Compare the original prompt with the enhanced prompt. Turn enhancement off if it adds unwanted details.
- Generate, download and inspect the result at full size; do not judge edge quality from a thumbnail.
reAPI offers a third-party playground and API at US$0.02 per 1K image and US$0.04 per 2K image, billed per delivered image. Thus 100 completed outputs cost US$2 or US$4 before other charges. This is reAPI’s tariff, not an official Alibaba API price. Check the provider’s current terms for commercial use and uploaded material.

Developers can follow its API reference: use model ID qwen-image-2.1, submit an asynchronous request, then poll the returned task ID. For self-hosting, vLLM-Omni documents an image API; you supply the GPU and pay its running costs. A model download, a shared demo and a hosted API are three different services.
Local setup, ComfyUI workflows and realistic VRAM expectations
Start with an updated ComfyUI installation and the Comfy-Org model package. Import the official text-to-image workflow or image-edit workflow. Use the matching 2.1 VAE and encoder rather than copying a previous Qwen workflow unchanged.

An INT8 configuration uses the following files. BF16 variants are also available. If a loader asks for a different precision variant, select the files you actually downloaded in that loader.
ComfyUI/models/diffusion_models/
 qwen_image_2.1_int8_convrot.safetensors
ComfyUI/models/text_encoders/
 qwen3vl_8b_int8_convrot.safetensors
ComfyUI/models/vae/
qwen_image_2.1_vae_bf16.safetensors- Update ComfyUI and load the appropriate official workflow JSON.
- Download the visual model, Qwen3-VL encoder and 2.1 VAE into the folders above; restart or refresh the model list.
- Select matching filenames in the loading nodes. Add a source image only for an editing workflow.
- Begin with one image at 1024 × 1024 and the workflow’s suggested settings. Confirm it runs before increasing resolution or references.
- Save the seed, model precision, resolution and settings for comparisons. Check the saved PNG’s alpha channel for transparency.
There is no single reliable “minimum VRAM” number. The vLLM recipe’s GB300 benchmark reports about 34GB peak memory for one BF16 configuration at 1024 × 1024 and 40 steps; that is datacenter hardware, not a desktop buying recommendation. The 16GB community result above uses quantization and a different stack. Neither proves that every 16GB machine can handle native 2K with ten references.
Quantization and CPU offload can help fit a model but may change speed or quality. Extra system RAM and SSD space are still needed. The optional 9B prompt-enhancement models are separate downloads, not a requirement for your first run. Existing GPUs are worth trying; buying one solely because the headline says “7B” is premature.
How it compares with other choices
| Model | Best reason to consider it | Main trade-off |
|---|---|---|
| Qwen-Image-2.1 | Native transparent assets plus generation and editing in one model. | Research license; reference complexity and hardware demand still matter. |
| Qwen-Image-Edit-2511 | Keep a proven existing editing workflow and compare familiar briefs. | An older dedicated editing model; do not assume its nodes or add-ons transfer to 2.1. |
| FLUX.2 [klein] 4B | Fast iteration and an Apache-2.0 4B weight option. | The 9B variant has different license terms; qualify the exact version. |

Keep the older model installed until 2.1 passes the edits you actually need: a face-preserving clothing change, a product label that must remain legible and a background replacement. A new model can improve one of these while regressing on another.

Black Forest Labs lists FLUX.2 klein 4B generation from US$0.014 for the first megapixel, with additional pixel and reference charges. That is not directly equivalent to reAPI’s flat 1K/2K tiers. Choose 2.1 for transparency experiments; consider klein 4B when iteration speed and permissive weight licensing matter more. This is a workflow comparison, not a matched image-quality ranking.
More context: our Qwen Image family review
NSFW support and commercial-use limits
Do not read “local” as an official promise of unrestricted NSFW support. Early users report different behavior between text generation and editing. A downloaded checkpoint, an optional prompt rewriter and a hosted provider’s moderation can each behave differently. reAPI documents moderation of inputs and outputs; its policies apply even when a model can produce something locally.
The Qwen Research License is equally important: it limits the provided materials to research/evaluation and requires a separate license for commercial use. The published contact is model-business@notice.qwencloud.com. Do not carry over Apache-2.0 assumptions from older Qwen releases, or assume that paying for a third-party API settles every usage-rights question.
Prompts and use cases worth testing
- Transparent assets: ask for one isolated subject, its material, lighting and an alpha background. Start without a floor or scenic backdrop that could conflict with transparency.
- Product edits: specify what changes and explicitly preserve shape, printed text and camera angle. Inspect those details after generation.
- Multiple references: identify inputs by order and give each one a role. Add references gradually instead of starting with ten.
- Typography: quote the exact text and specify its placement. Proofread every character, especially multilingual copy.
- Anime and portraits: test facial identity and small details across several edits. The model is not a guarantee of a specific artist’s style or perfect anatomy.
Example brief: “Create one paper-cut orange flower sticker with a transparent RGBA background. Keep the petals crisp and leave empty space around the subject. No lettering.” For editing: “Replace only the blue backdrop with pale green. Preserve the bottle, printed label, reflections and camera angle.” These are suggested prompts, not recorded benchmark outputs.
FAQ and verdict
Is Qwen-Image-2.1 free?
The weights are downloadable without a per-image model fee, but local hardware, electricity and rental GPUs are not free. The research license restricts use. Hosted services have their own charges and limits.
Does 7B mean it works on an 8GB graphics card?
No. The visual generator is only one component. Encoder weights, the VAE, intermediate tensors, resolution and reference images also consume memory. Look for a tested configuration matching your hardware.
Can I use old Qwen LoRAs and workflows?
Do not assume compatibility. Start with the official 2.1 templates and check whether each adapter explicitly supports this architecture. A familiar filename is not sufficient.
Why is my “transparent” image opaque?
Check the output format and actual alpha channel. A JPEG cannot preserve transparency. Remove conflicting background instructions and inspect the asset against dark and light surfaces.
Should I switch now?
For research into cutouts, layers and localized editing, Qwen-Image-2.1 is worth a focused trial. Start with the official demo, then reproduce a small set of useful briefs locally if your hardware allows it. Keep a known-good alternative until consistency, speed and licensing fit your workflow.
For paid production, treat licensing as a selection criterion from the beginning. Strong sample images alone do not make a model the right business choice.
Related Reviews
Qwen 3.8 Review: Benchmarks, Local Setup, GPU Requirements and NSFW Policy

6 Best Picture-to-Drawing Converters in 2026
Ideogram 4 Review: Censorship Bypass, NSFW Policy, Text AI and ComfyUI Workflow

Canva Craft Review: 2K Images, Wide Formats, Text and Editing Limits
Illustrious XL Review: Setup, LoRA, VRAM, Prompts and NSFW Local Use
GPT-6 Astra Review: Pricing, API Access, Strengths and Limits